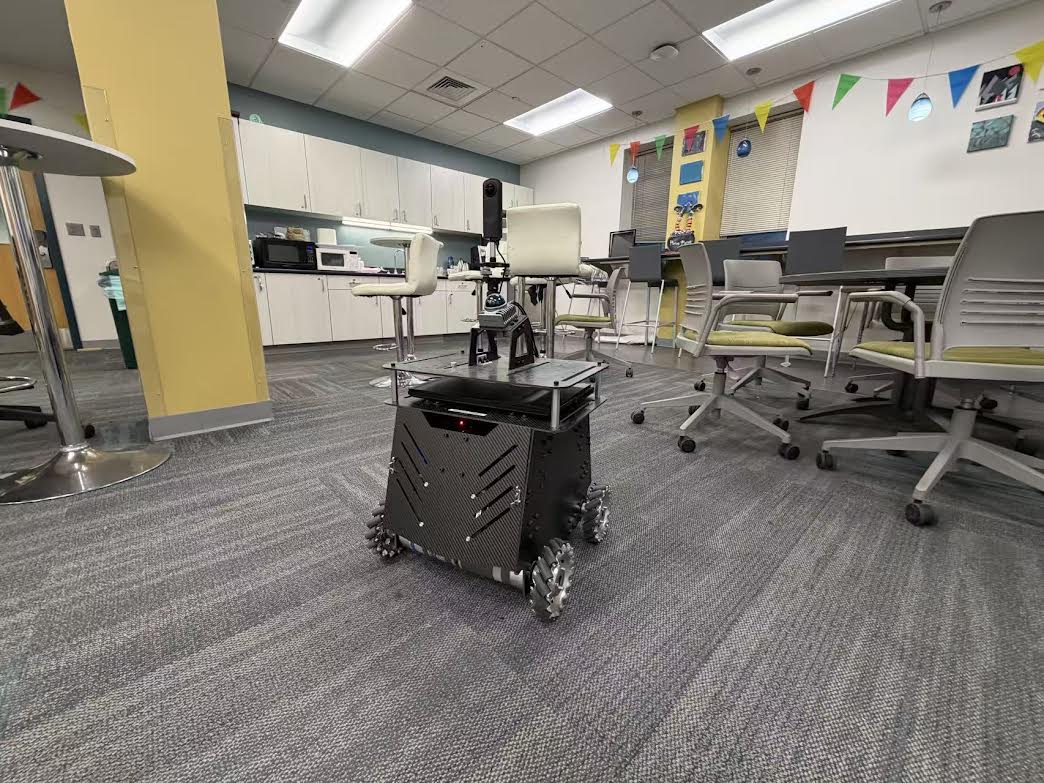
Most robot navigation benchmarks hand systems the answer before the test begins — predefined maps, labeled objects, structured environments. Carnegie Mellon University's Robotics Institute is deliberately removing that safety net. Its next Vision-Language-Navigation (VLN) Challenge strips out "ground truth" entirely, forcing competing systems to interpret raw sensor data, reason about unfamiliar spaces, and follow natural language instructions without any pre-loaded shortcuts.
- What Is the CMU Vision-Language-Navigation Challenge?
- Why Removing Ground Truth Changes Everything
- How the Challenge Works: From Simulation to Real Robots
- What Applications Does This Research Unlock?
- What This Means for Robotics
- Frequently Asked Questions
What Is the CMU Vision-Language-Navigation Challenge?
The VLN Challenge is a research competition hosted by Carnegie Mellon University's Robotics Institute, testing how well autonomous systems can interpret natural language instructions and navigate real, unstructured physical environments without predefined maps or labeled object data. Teams build the reasoning software; CMU provides the hardware platform.
The challenge sits at the heart of a field increasingly called Physical AI — the discipline of translating linguistic and perceptual understanding into reliable, embodied action. Getting a robot to hear "go to the kitchen and find something to sit on" and actually execute that task, in a building it has never seen, remains one of the hardest open problems in robotics. According to Carnegie Mellon's Robotics Institute, this phase of the competition is specifically designed to close the gap between polished lab demonstrations and genuine autonomous capability.
Why Removing Ground Truth Changes Everything
Eliminating ground truth — the predefined labels, object identities, and spatial coordinates that most benchmarks silently provide — is the single most significant design decision in this challenge iteration. It forces systems to do what humans do naturally: arrive somewhere new and figure it out.
In conventional VLN benchmarks, a robot might "know" that the object in front of it is a chair, because a dataset tag says so. Here, systems must infer that from raw LiDAR (light detection and ranging, a sensor that builds 3D point clouds by firing laser pulses) data and 360-degree camera feeds — the same inputs a real deployment would provide.
The deeper demand is semantic and spatial reasoning: understanding not just what an object is, but what role it plays in a spatial context. Jingfan Tang, an RI exchange student from Shanghai Jiao Tong University coordinating the challenge, explained the distinction clearly: "A hallway isn't just a narrow space. It connects different rooms and shapes how people move through a building." A system that can only classify a hallway as "corridor" without grasping its connective function will make poor navigational decisions the moment instructions become contextual — "meet me by the hallway near the conference room."
This is precisely where current large language model-based navigation systems tend to break down. They can parse instructions fluently but lose coherence when their spatial model of an environment is ambiguous or incomplete.
How the Challenge Works: From Simulation to Real Robots
The competition follows a two-phase structure designed to progressively raise the difficulty floor. Participating teams begin in a custom simulation environment, developing and stress-testing their reasoning architectures without hardware constraints. The second phase transitions to real-robot testing on CMU's physical platform — a system equipped with 3D LiDAR and a 360-degree camera — where sensor noise, lighting variation, and physical uncertainty become unavoidable factors.
| Phase | Environment | Primary Focus |
|---|---|---|
| Phase 1 | Custom simulation | Algorithm development, semantic reasoning |
| Phase 2 | Real-robot hardware | Sensor integration, real-world robustness |
| Final presentation | IROS 2026, Pittsburgh | Results and research exchange |
Teams are responsible solely for the reasoning and navigation software stack — the perception-to-decision pipeline that turns sensor data and language into movement commands. CMU provides the physical platform, keeping the barrier to entry focused on intelligence rather than hardware access.
The challenge will conclude with a workshop at the 2026 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), held in Pittsburgh, where teams present findings to the broader research community. RI Systems Scientist Ji Zhang, who advises the research group, noted that CMU is well-positioned for this precisely because of the institute's track record building systems that operate outside controlled lab conditions.
What Applications Does This Research Unlock?
The technical advances targeted by this challenge have direct downstream implications across several robotics deployment categories. Ji Zhang was direct about the stakes: "Advances in vision-language navigation could lead to more capable home assistants, improved search-and-rescue robots and smarter tools for industry."
Breaking that down by sector:
Service and domestic robotics — A robot assistant that can receive spoken instructions and navigate an unfamiliar home without a pre-loaded floor plan would represent a step-change in usability. Current home robots largely depend on initial mapping sessions before they can function reliably.
Search and rescue — Disaster environments are the antithesis of structured datasets. Buildings collapse, corridors become impassable, and no prior map exists. Robots that can reason spatially from live sensor data and respond to operator instructions in natural language could operate where GPS-dependent or map-reliant systems fail entirely.
Industrial and logistics automation — Warehouses change layout. New facilities require re-mapping. A navigation system that infers spatial relationships from raw observation rather than pre-programmed maps reduces the integration overhead for deploying autonomous mobile robots in dynamic environments. You can browse industrial robots on Robot Overflow to see how current-generation systems handle structured environments — the VLN research trajectory points toward where the next generation needs to go.
What This Means for Robotics
The CMU VLN Challenge is a calibration tool for the entire embodied AI field — it forces a reckoning between benchmark performance and genuine robustness.
For hardware developers, the challenge signals where sensor suites need to improve. Systems relying purely on LiDAR struggle with semantic understanding; those relying purely on cameras struggle with depth. The combination required here pushes sensor fusion research.
For software and AI teams, the removal of ground truth is a direct challenge to current foundation model approaches. LLMs and vision-language models have demonstrated strong instruction-following in structured settings. The question this challenge poses is whether that capability survives contact with raw, noisy, unlabeled physical reality.
For buyers and operators of autonomous mobile robots (AMRs) — particularly in logistics, healthcare, and facilities management — the research pipeline feeding into challenges like this one is directly upstream of the next generation of deployable hardware. Systems that can navigate without pre-mapping represent a significant reduction in deployment friction. If you're evaluating used cobots for sale or autonomous mobile platforms today, the capabilities being stress-tested here represent what the commercial market will deliver within the next several hardware generations.
The broader significance is standard-setting. One explicit goal of the challenge is to establish a new global benchmark for Physical AI — ensuring that intelligence claims made in research translate into reliable autonomous action in unstructured environments.