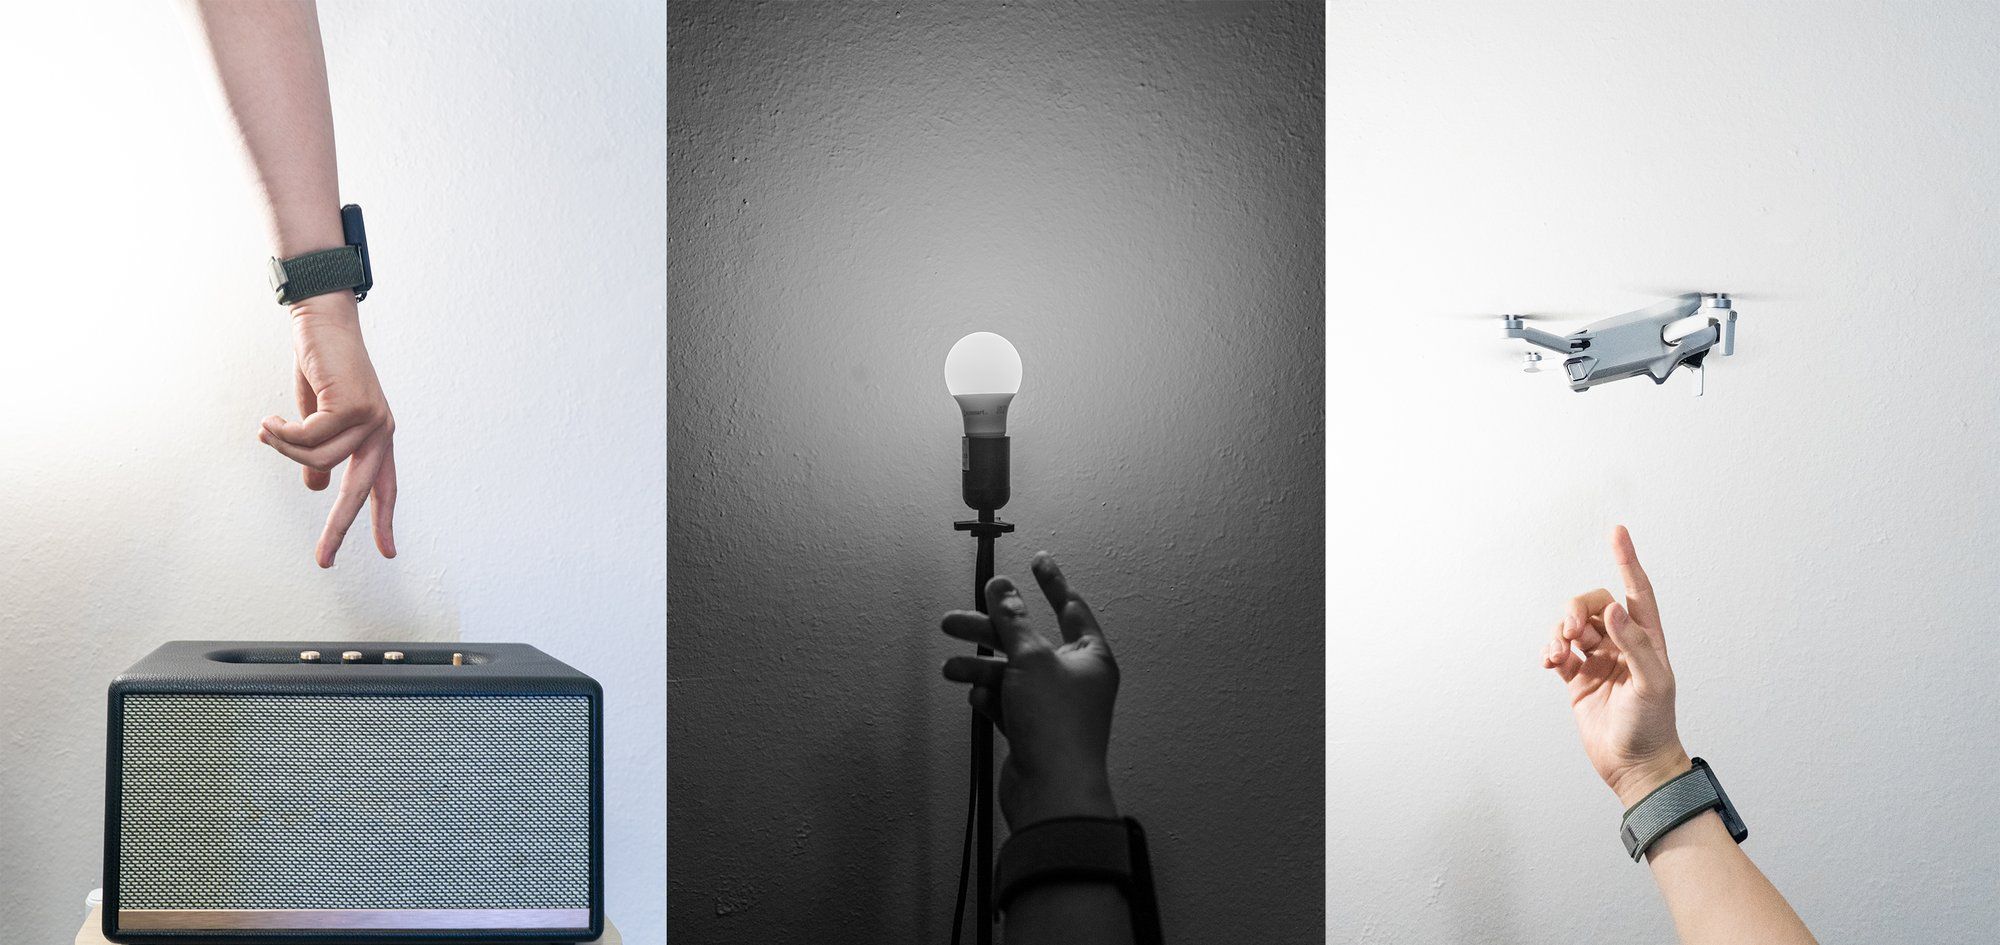
The physical AI industry has poured billions into smarter actuators, dexterous hands, and foundation models — and largely neglected the human side of the loop. Wetour Robotics argues that the real bottleneck is not robot capability but the interface that lets humans participate in real time, especially when hands, eyes, or voice are occupied with the task at hand.
- The Interface Bottleneck in Physical AI
- Wetour Robotics' Spatial Intent Fusion Approach
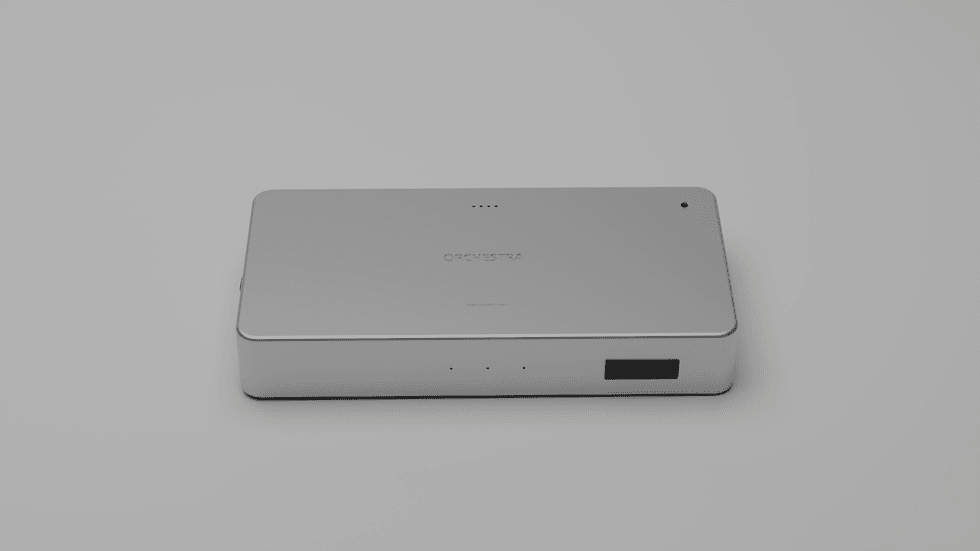
- How Orchestra OS Works: Architecture and Components
- The Trade-Offs: Where the Technology Still Falls Short
- What This Means for Robotics and Automation
- Frequently Asked Questions
The Interface Bottleneck in Physical AI
The past three years have delivered leapfrog advances in robot hardware and embodied AI — from Boston Dynamics' agile manipulation to Google DeepMind's Gemini Robotics models. Yet every one of those systems still depends on the same three input modalities that have dominated human-machine interaction for four decades: screens, buttons, and voice. Those modalities assume the user can stop, look down, and translate intent into structured commands — an assumption that breaks the moment the work moves into a real environment. A field technician on a wind turbine, both hands on a wrench, cannot pause to tap a tablet. A logistics worker on a loading dock, eyes on a pallet, cannot pull out a phone. In any setting where hands are occupied, eyes are committed, or speech is impractical, the conventional interface stack quietly fails. According to a technical analysis by Wetour Robotics (via IEEE Spectrum), this hidden bottleneck is becoming as consequential as any hardware limitation on the robot side — and solving it requires treating the human body as a first-class node in the computing network.
Wetour Robotics' Spatial Intent Fusion Approach
Wetour Robotics calls its solution Spatial Intent Fusion: the simultaneous processing of three streams of human-centered information — spatial position, visual context, and gestural intent — fused into a single real-time command for any connected physical device. Unlike voice or touch, this approach does not require the user to stop or disengage from their primary task. Instead, the system reads intent from where the body already is, what the eyes are already looking at, and what the muscles are already preparing to do. The core claim is that a single modality observed in isolation is ambiguous — a raised arm could mean "stop," "reach," or "stretch." Combining location, gaze, and muscle activation in a single inference engine resolves that ambiguity at the operating system level. The company's stated goal is to make the interface feel closed rather than mediated, with end-to-end latency held under 100 milliseconds — the threshold at which real-time interaction feels natural rather than laggy.
How Orchestra OS Works: Architecture and Components
Orchestra is not a single device but a layered platform built to be sensor-flexible and actuator-agnostic. The architecture decomposes into three perception layers and four coordination engines.
Perception Layers:
| Layer | Function | Key Property |
|---|---|---|
| VisionLink | Visual/spatial perception from cameras | Real-time object ID, distance estimation, environmental context |
| Conductor | Biosignal pipeline from surface EMG wristband | Detects motor unit action potentials 50–80 ms before visible motion |
| Orchestra OS | Compute and orchestration core (NVIDIA Jetson Orin Nano Super) | Edge inference, no cloud dependency on critical path |
The four coordination engines — Perception, Intent, Orchestration, and Safety — run on the Jetson Orin Nano Super, keeping the entire control loop at the edge. The Intent Engine performs the actual Spatial Intent Fusion, resolving across modalities what the user is trying to do. The Safety Engine arbitrates conflicting commands and enforces operational envelopes, a critical requirement for any system bridging human intent and physical machinery.
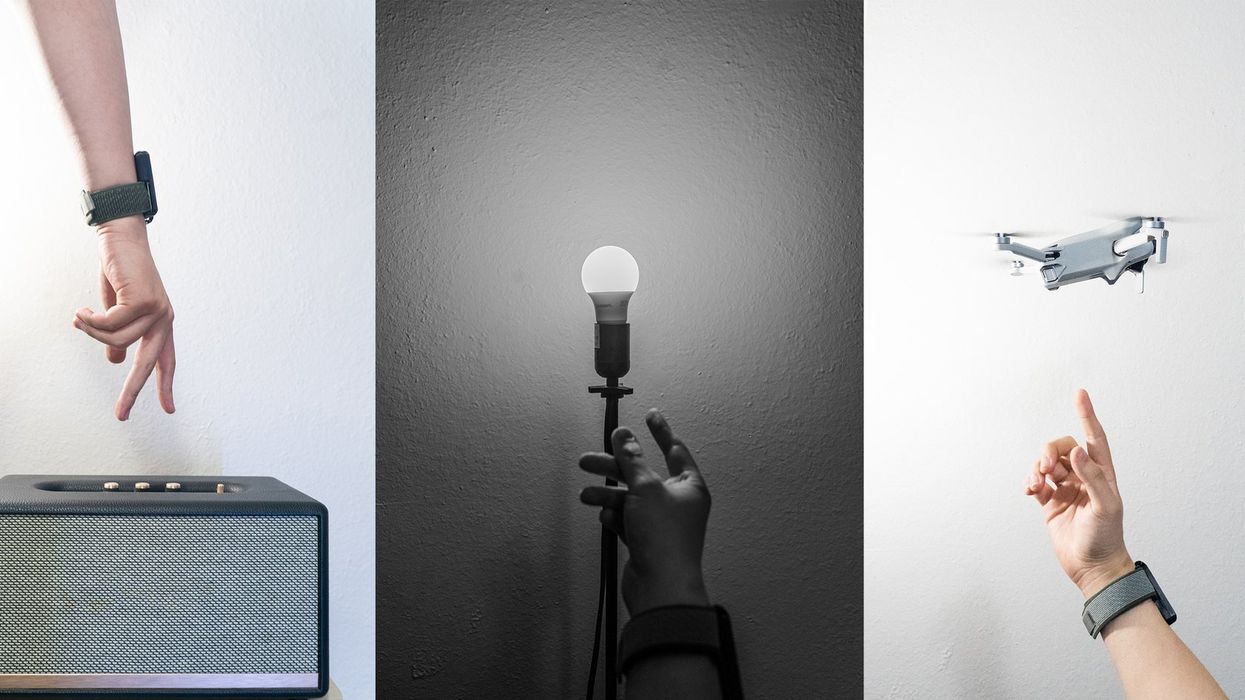
The technically distinctive property of surface electromyography (sEMG) is that it can read intent before the body acts. Motor unit action potentials appear at the skin surface roughly 50 to 80 milliseconds before a finger completes the corresponding gesture. Wetour Robotics calls this pre-motion intent sensing, and it is what allows Orchestra to anticipate user intent rather than react to it — a capability that no screen, button, or voice interface can replicate.
The Trade-Offs: Where the Technology Still Falls Short
No system bridging the human body and digital machinery is finished. Wetour Robotics acknowledges three open challenges and addresses each with a deliberate trade-off.
Baseline stability of sEMG under motion. In a stationary user, continuous gesture recognition from surface EMG is reliable. But once the user is walking, climbing, or otherwise moving, motion artifacts and electrode drift degrade the signal. The company's response is pragmatic: Orchestra defaults to a smaller set of robust discrete gestures in complex operating environments and reserves continuous control modes for contexts where the signal-to-noise ratio supports them.
Miniaturization of edge AI compute. Running the full perception-to-actuation loop at the edge — including vision models, EMG classification, and protocol translation — requires real on-device inference. Wetour Robotics uses a compact carrier board with a thermal design and battery module sized for all-day wearability, but miniature edge compute still involves trading off between capacity, battery life, and form factor.
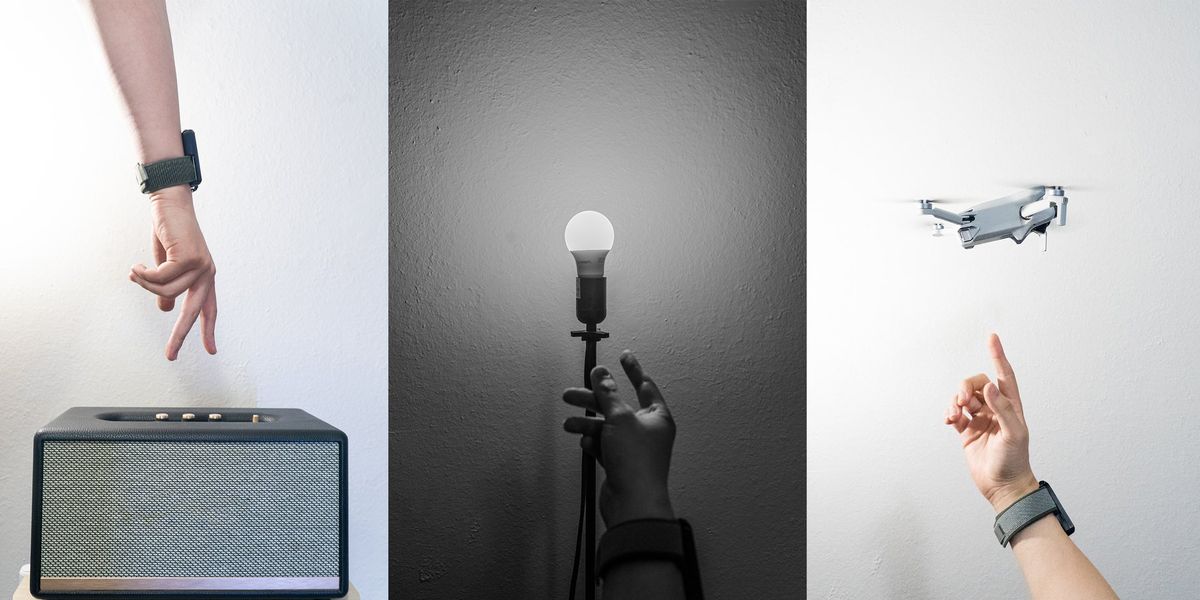
Heterogeneity of third-party device protocols. The actuator side of the loop is a fragmented landscape of different manufacturers, command interfaces, communication stacks, and safety conventions. Rather than standardize, Orchestra uses an AI-agent layer to negotiate connection and translate protocols adaptively, so the same human intent can drive a drone, a used industrial robot, or a mobility device.
What This Means for Robotics and Automation
The broader implication for the robotics industry is twofold. First, smarter interfaces expand the addressable use cases for existing robot hardware. A warehouse robot that already works autonomously in structured aisles becomes far more useful when a floor supervisor can redirect it with a glance and a subtle hand gesture — no tablet, no voice command, no stop to the workflow. For buyers evaluating robot deployments, interface capability is becoming a purchasing criterion alongside payload, reach, and cycle time.
Second, treating the human body as a first-class node in the computing loop produces the kind of grounded, in-the-wild human-machine interaction data that the broader Physical AI ecosystem needs. Every natural interaction between a human and the physical world is a potential training signal for foundation models — and most of those interactions are currently invisible to any computing system. Wetour Robotics' approach effectively turns every operator into a data generator for the next generation of embodied AI, including humanoid robots.
For potential buyers, the key question is not whether your robot is smart enough — it is whether your operators can communicate with it without stopping their work. The cost of retraining, of workflow interruptions, and of adoption friction often exceeds the cost of the robot itself. Interface-first systems like Orchestra may offer a better return on that total cost of ownership than simply upgrading the robot's on-board intelligence.
Conclusion
Physical AI has advanced dramatically on the robot side of the loop, but the human side remains constrained by interfaces designed for desk-bound work. Wetour Robotics' Spatial Intent Fusion approach offers a compelling alternative: treat the body as the interface, fuse multiple intent signals at the edge with sub-100 ms latency, and let operators stay focused on their task rather than on the tool. The next wave of productivity in automation may not come from smarter robots — but from smarter ways for humans to talk to the ones we already have.