Teaching robots new manipulation skills typically requires hundreds of hours of task-specific data. A new framework from researchers demonstrates that robots can learn reusable reward functions from as few as five demonstrations — and generalize them to entirely new positions, objects, and viewpoints without retraining. This breakthrough could dramatically accelerate real-world robot deployment across factories and warehouses by removing a major bottleneck in reinforcement learning for robotics.
- Why do robot reward functions fail in the real world?
- How does the invariant reward framework work?
- What results did the experiments show?
- How does this accelerate downstream policy learning?
- What does zero-shot generalization mean for robotics?
- What This Means for Robotics
- Frequently Asked Questions
Why do robot reward functions fail in the real world?
Reward functions define what a robot should achieve in reinforcement learning, but traditional vision-based rewards memorize specific pixel patterns rather than the task's underlying goal. When the camera angle shifts, the object changes, or the lighting differs, these rewards break — forcing engineers to manually redesign them for each environment.
According to the researchers in their preprint on arXiv, "recent vision-based reward models tend to memorize specific pixel distributions and fail to generalize beyond their training conditions." This overfitting is a fundamental challenge in open-world manipulation problems, where a single task can appear in numerous variants through different object instances, positions, and camera viewpoints. A reward trained to recognise a red cup on a white table fails when the cup is blue, the table is wooden, or the robot approaches from the opposite side. The cost of this fragility is high: each new deployment environment effectively requires a fresh reward engineering cycle, limiting scalability.
How does the invariant reward framework work?
The framework shifts from fitting visual features to discovering behavioral invariants: task-level properties that remain constant across diverse visual instantiations. It uses two coupled components — a structural reward formulation that encodes task strategies and physical constraints while preserving optimal policy invariance, and a hybrid symbolic-numerical procedure that extracts these invariants from demonstrations without any online interaction.
Think of it as teaching the robot the puzzle's logic rather than the specific colors of the pieces — then it can solve any variation. Unlike end-to-end neural reward models that learn correlations between pixels and success, this approach explicitly searches for symbolic rules that hold across visual transformations. The hybrid procedure first extracts candidate symbolic predicates from demonstrations, then validates them against physical consistency constraints. The result is a reward function expressed in terms of object relations and geometry rather than raw image features. Where the analogy breaks down is that the framework retains numerical components for fine-grained control; it is not purely symbolic but uses symbols to guide the numerical reward computation.
What results did the experiments show?
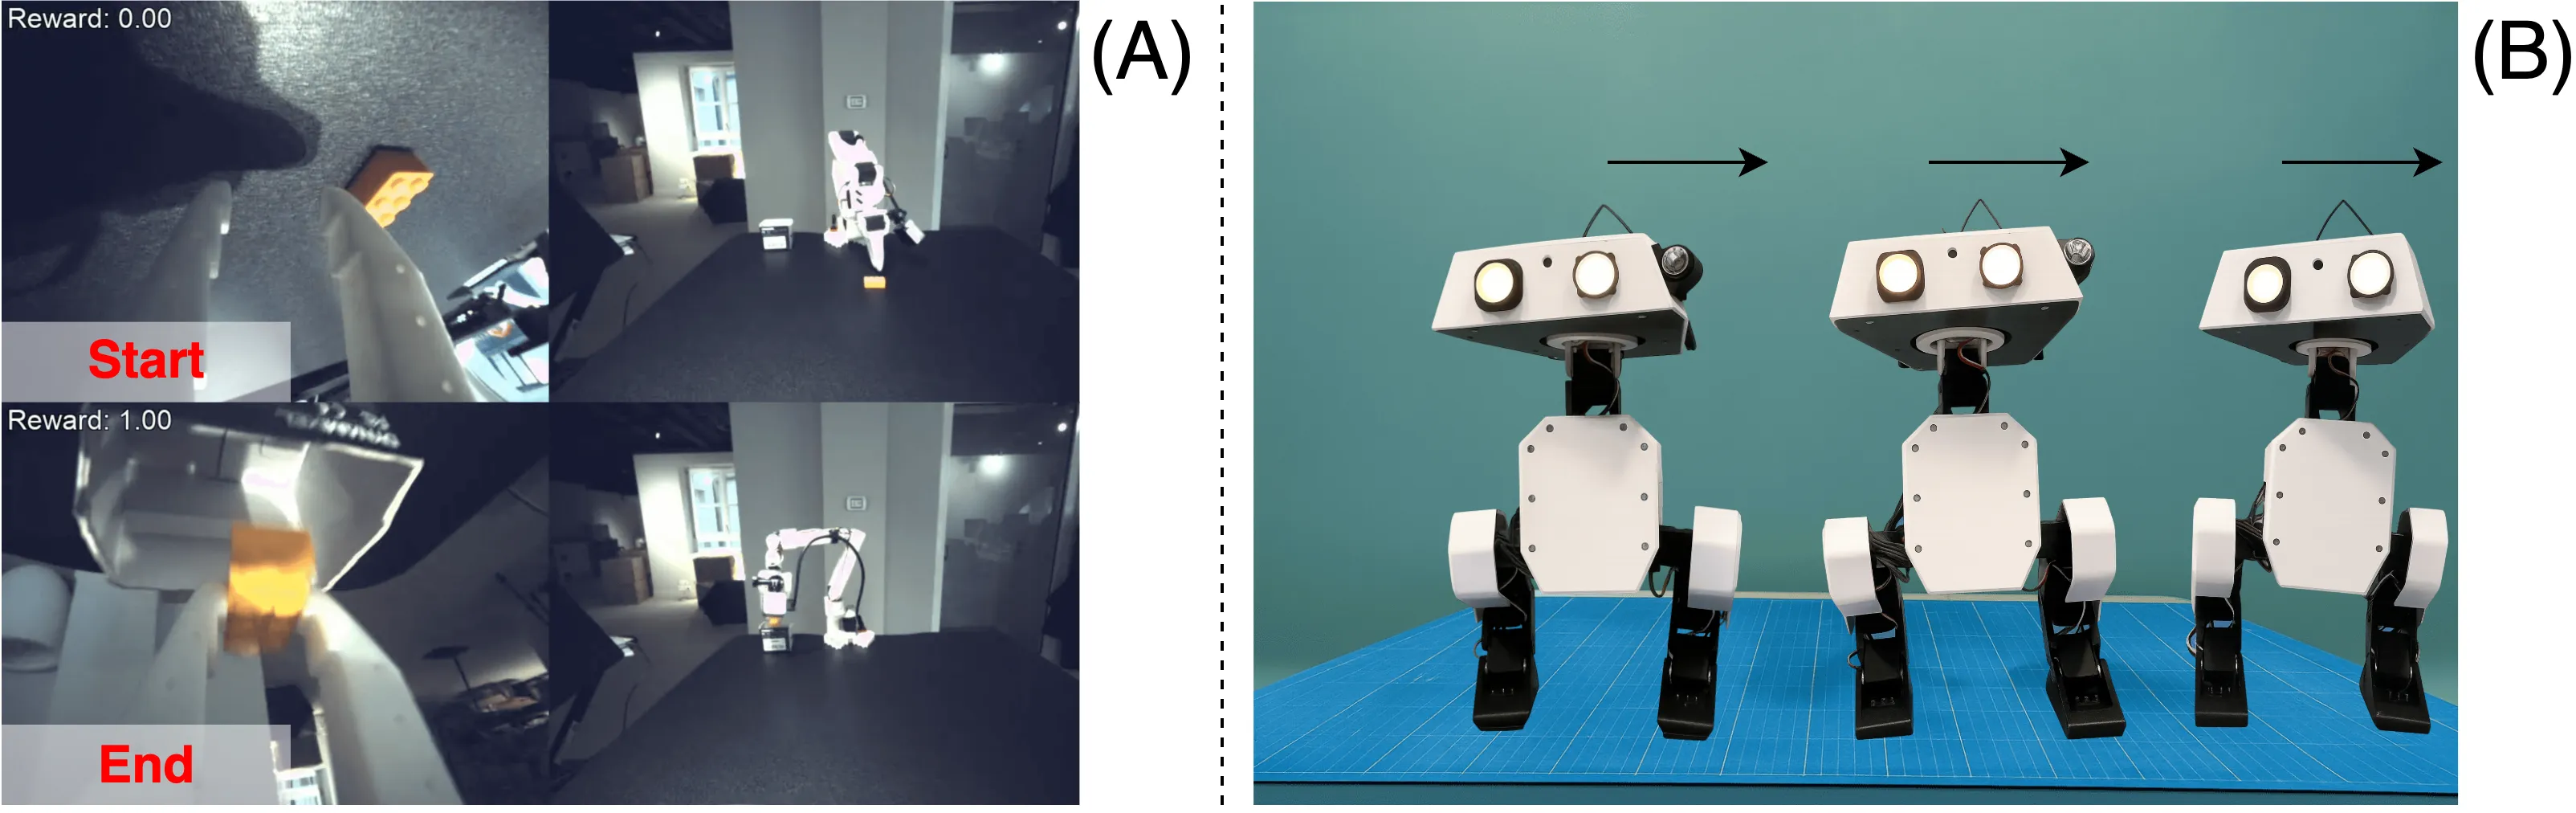
The method was tested on eight Meta-World manipulation tasks and three Franka real robot tasks. It achieved stronger process alignment and policy rollout ranking than baseline methods. In real-world out-of-distribution tests, the same learned reward generalized zero-shot to changes in position, viewpoint, and object appearance — a result the authors describe as enabling "a single reward representation to be reused across diverse task variants in practice."
| Approach | Data Required | Generalization | Real-World OOD |
|---|---|---|---|
| Traditional reward learning | 100+ demos | Poor | Not demonstrated |
| Invariant reward framework | 5 demos | Zero-shot position/viewpoint/object | Demonstrated across 3 experiments |
| Baseline vision models | 50+ demos | Limited (minor viewpoint shifts) | Fails on OOD |
The zero-shot capability is particularly significant: the reward learned in a lab setup with a single object instance directly transferred to new object shapes, different table heights, and lighting conditions that the system had never encountered. The authors note that "the same learned reward generalizes zero-shot to position, viewpoint, and object variations," which directly addresses one of the largest barriers to deploying RL in production environments.
How does this accelerate downstream policy learning?
By providing a stable and generalizable reward signal, the framework enables downstream RL policies to learn faster and transfer across tasks. The invariant reward reduces the search space for the policy, allowing it to focus on motor control rather than re-learning task goals for each variation.
In traditional setups, a robot must be re-trained from scratch for every new object position or camera placement — each variant effectively becomes a new task. With invariant rewards, the policy can be trained once and then fine-tuned for specific environments using the same reward function. The experiments showed stronger process alignment, meaning the policies not only reached the goal but did so through strategies that mirrored the demonstrated behavior. For robotics integrators, this translates to reduced engineering time: rather than weeks of reward tuning per workstation, a general reward can be learned from a handful of human demonstrations and then applied across an entire factory line.
What does zero-shot generalization mean for robotics?
Zero-shot generalization means a robot can pick up an object it has never seen, at a position it has never reached, under lighting conditions it never experienced — using the same reward function learned from just five initial demonstrations. This is a critical capability for open-world manipulation where every environment is unique.
For warehouse automation, this could mean a single robot arm handling incoming parcels of arbitrary size and placement without prior calibration. In manufacturing, a cobot could learn a new assembly step from five operator demonstrations and then execute it on any workbench layout. The researchers demonstrated exactly this: their real-world out-of-distribution experiments included shifting the target object across the workspace, rotating the camera to a completely new angle, and swapping the object for one of different shape and color — all handled by the same learned reward. The implications for deployment cost are substantial: instead of paying system integrators for site-specific reward engineering, end users could receive a pre-trained reward that adapts on the fly.
What This Means for Robotics
For robotics teams evaluating reinforcement learning for manipulation, this framework directly addresses the data efficiency and generalisation problems that have kept RL-based automation out of most commercial deployments. The ability to learn from five demonstrations rather than hundreds cuts the barrier to entry for small and medium-sized businesses. Moreover, the zero-shot generalisation means that a single reward can be shared across multiple workcells, reducing the total cost of ownership.
For buyers looking at used collaborative robots on Robot Overflow or used industrial robots, this research points toward a future where robots become more adaptable without requiring expensive custom programming. While the framework is still in the research stage, its minimal data requirements and proven real-world OOD performance suggest that commercial toolkits incorporating similar ideas could appear within one to two years. Roboticists should monitor the hybrid symbolic-numerical approach as a potential alternative to purely neural reward models.
Conclusion
Learning invariant rewards from just five demonstrations represents a practical step toward deployable reinforcement learning in robotics. By shifting from pixel-fitting to behavioral invariants, the framework solves the generalisation problem that has limited real-world adoption of vision-based rewards. As roboticists seek to reduce the data and engineering cost of automation, this approach offers a path to robots that truly understand tasks — not just the specific visual conditions under which they were taught.