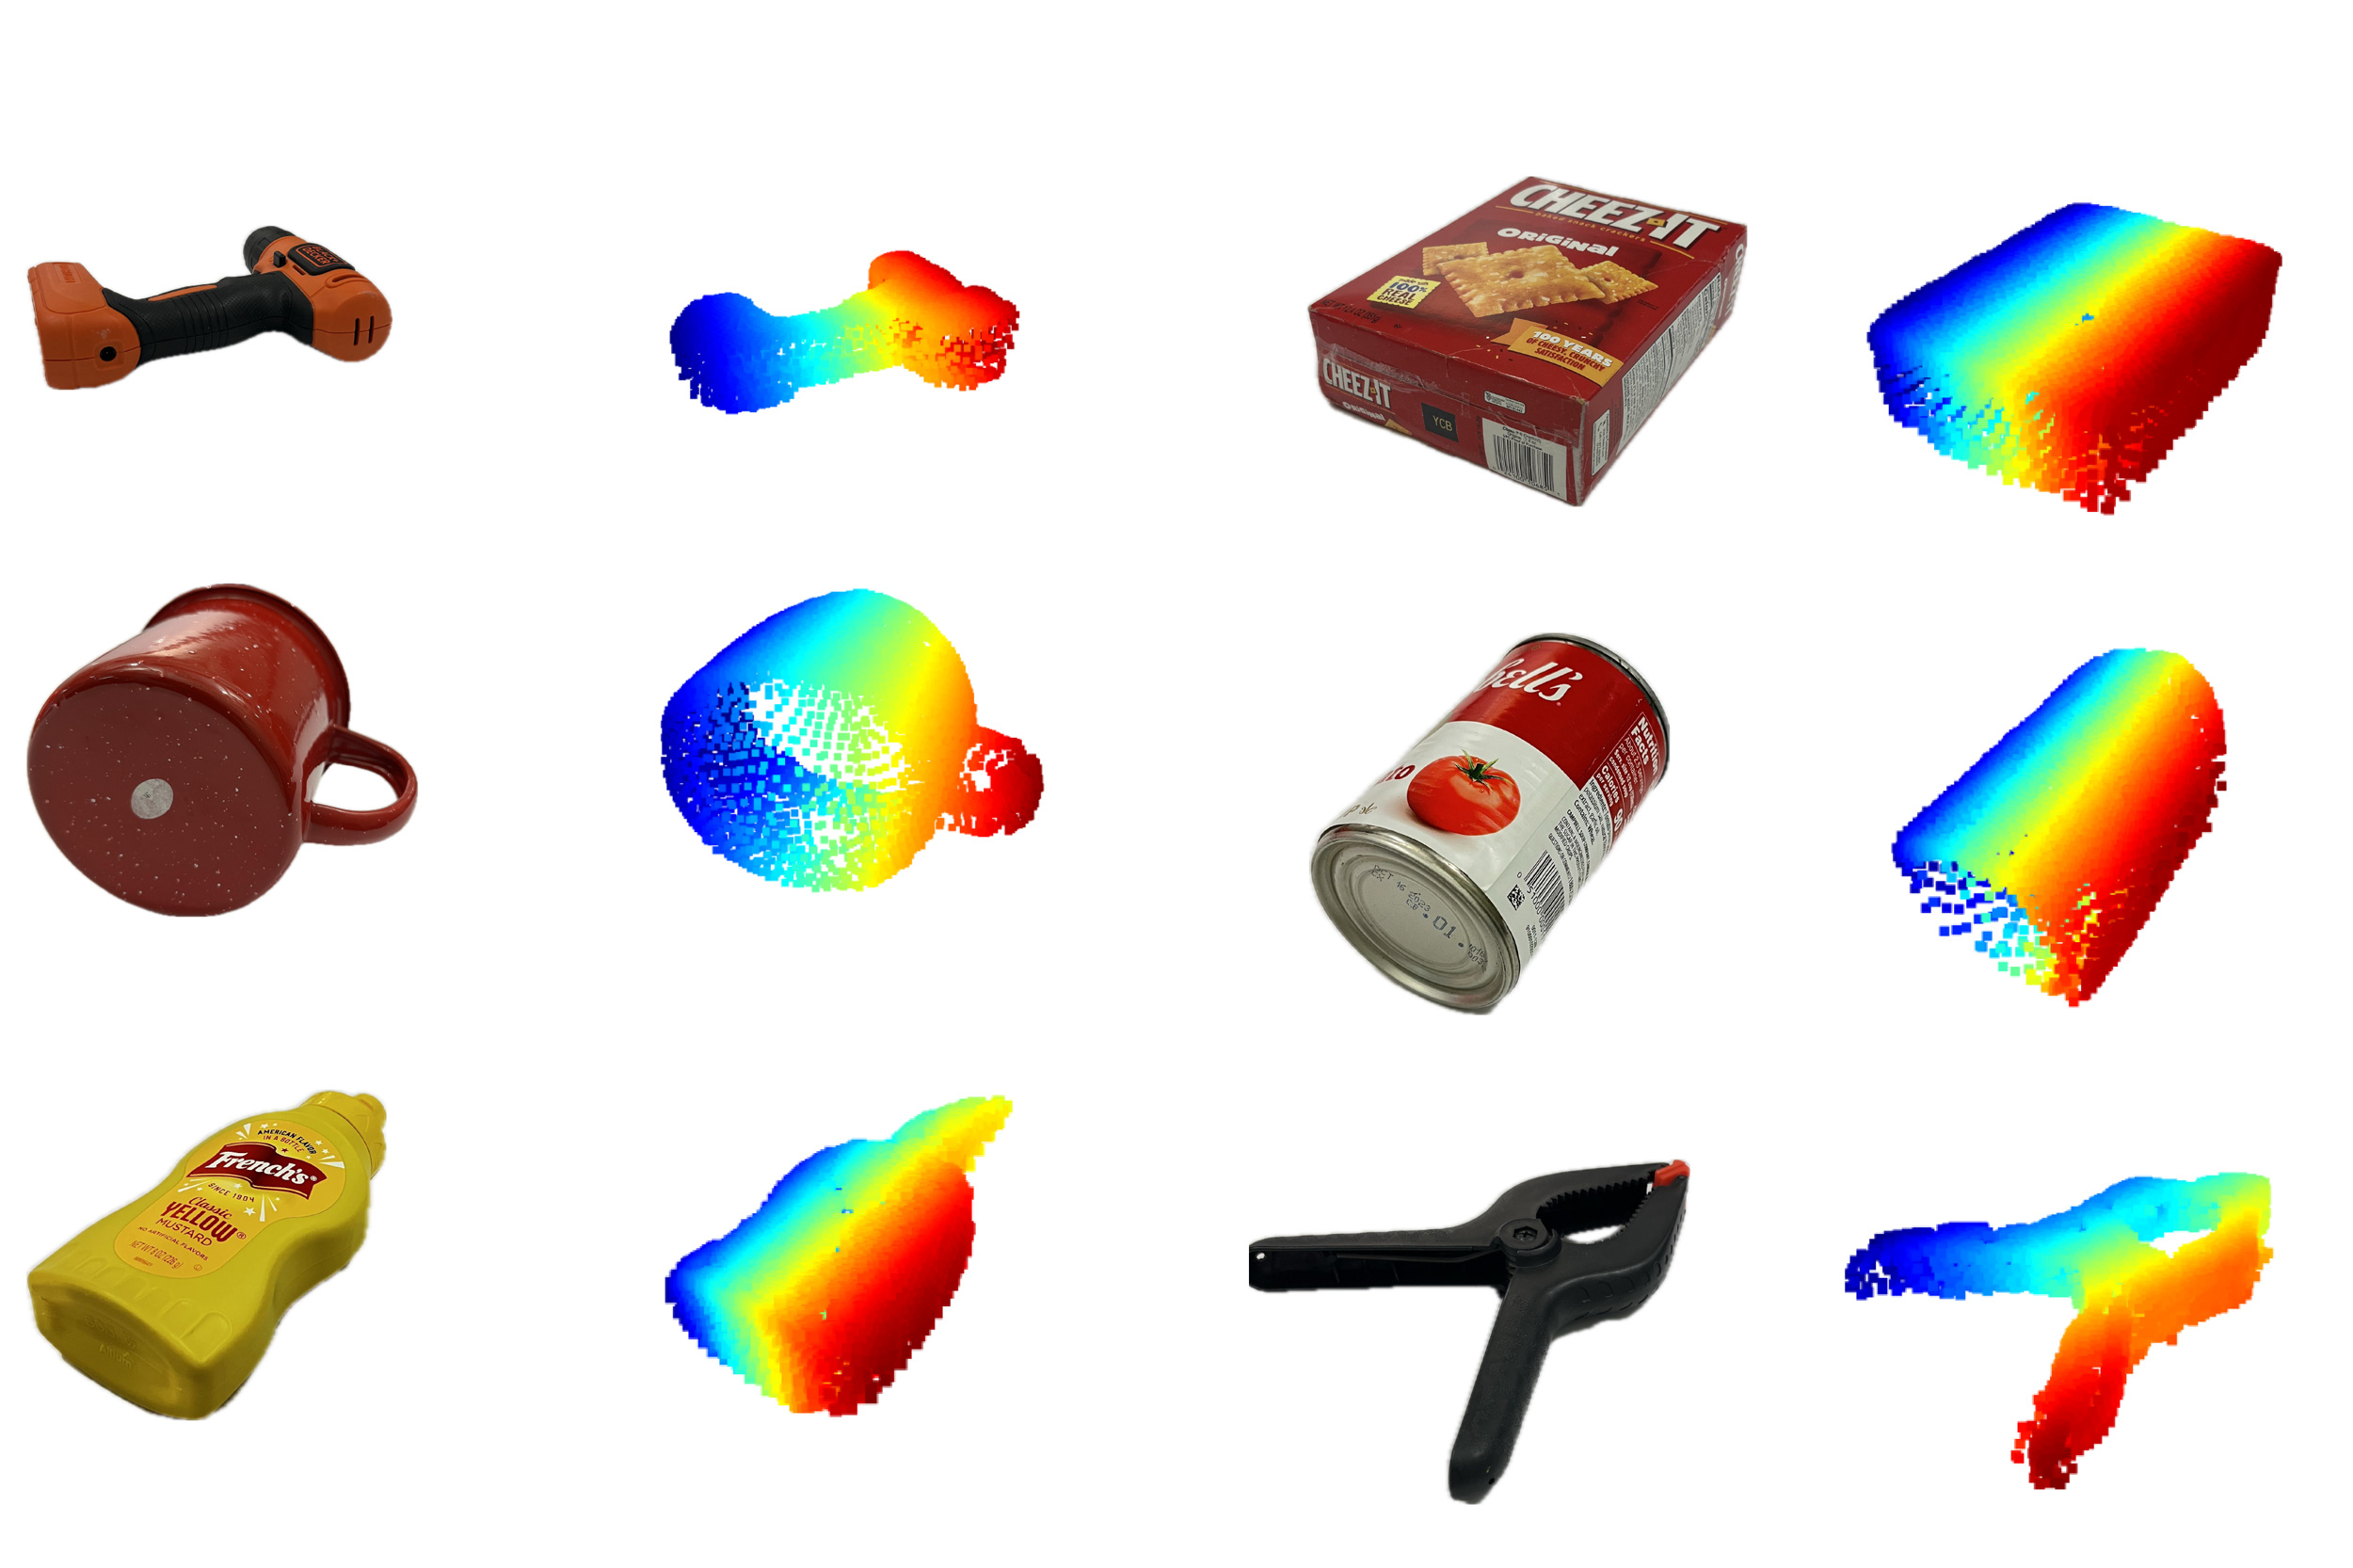
MIT researchers utilized specially trained generative AI models to create a system that can complete the shape of hidden 3D objects. Credit: Courtesy of the researchers.
Robots operating in warehouses and smart homes have a fundamental blind spot: anything blocked from their cameras simply doesn't exist to them. MIT researchers have now deployed generative AI to fix that, using millimeter-wave wireless signals and specially trained AI models to reconstruct hidden objects and entire rooms with nearly 20% greater accuracy than previous methods — without a single camera.
- Why Camera-Based Robot Vision Has a Structural Weakness
- How Wave-Former Reconstructs Hidden Objects Through Walls
- RISE: Mapping Entire Rooms From a Single Radar
- The Training Data Problem — and How MIT Solved It
- What This Means for Warehouse and Industrial Robotics
- Frequently Asked Questions
Why Camera-Based Robot Vision Has a Structural Weakness
Camera-dependent robot perception fails the moment an object goes out of line of sight — behind packaging, under debris, or around a corner. This isn't an edge case; it's a daily operational reality in warehouses, logistics hubs, and home environments where robots need to locate, identify, and grasp objects they cannot directly see.
Existing workarounds — multiple cameras, structured light, LiDAR — all share the same constraint: they require a clear optical path. The moment cardboard, drywall, plastic, or even dense fabric enters the equation, the robot is effectively blind. This limitation drives costly errors in fulfillment operations, including misidentified packed items and failed grasps that halt production lines.
The MIT Signal Kinetics group, led by Associate Professor Fadel Adib, has spent over a decade building alternatives using millimeter-wave (mmWave) radar signals — the same frequency band used in modern Wi-Fi — which pass through common obstructions and reflect off concealed objects. The challenge, until now, was that those reflections were too incomplete to be useful for precise manipulation.
How Wave-Former Reconstructs Hidden Objects Through Walls
Wave-Former, MIT's new system, combines mmWave radar with a generative AI model to reconstruct the full 3D shape of objects hidden behind obstructions — achieving close to 20% accuracy improvement over prior state-of-the-art methods across roughly 70 everyday objects including cans, boxes, utensils, and fruit.
The core physics problem is specularity: mmWave signals reflect off surfaces in a single direction, like light off a mirror. The radar sensor only captures reflections directed back at it, meaning the top surface of a hidden object is partially visible while its sides and underside are effectively invisible. Prior systems tried to interpret these incomplete point clouds using physics-based rules alone — a fundamentally limited approach.
Wave-Former's pipeline works in three stages. First, it builds a partial reconstruction of the hidden object from the raw mmWave reflections. Second, it feeds that partial shape to a generative AI model trained to predict plausible completions. Third, it iteratively refines the surface until it converges on a full 3D reconstruction. The result: robots can not only detect a hidden object, but understand its geometry well enough to plan a reliable grasp.
According to Robohub's coverage of the research, the system was validated across objects concealed behind or under cardboard, wood, drywall, plastic, and fabric — the exact materials present in real warehouse and logistics environments.
RISE: Mapping Entire Rooms From a Single Radar
MIT's second system, RISE (Radar-based Indoor Scene Understanding), reconstructs complete room layouts — including furniture placement — using reflections from a single stationary mmWave radar. It achieves roughly twice the spatial precision of existing techniques and requires no mobile sensor platform.
Most current approaches to wireless scene reconstruction require a radar mounted on a moving robot to sweep the environment — a significant operational constraint. RISE takes a different approach: it exploits multipath reflections generated by humans moving naturally through a room.
When a person moves, mmWave signals bounce off them, then reflect again off walls and furniture before returning to the radar. These secondary echoes — typically discarded as noise under the label "ghost signals" — actually encode spatial information about the room's layout. As the person moves, the ghost signals shift, and their changing positions reveal the geometry of surrounding surfaces.
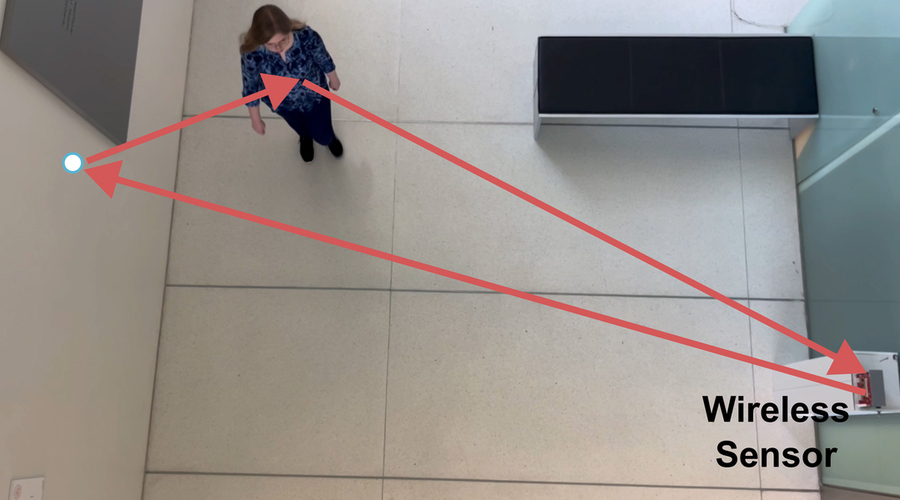 The team also built an expanded system that fully reconstructs entire indoor scenes by leveraging wireless signal reflections off humans moving in a room. Credit: Courtesy of the researchers.
RISE was validated on more than 100 human trajectories captured by a single stationary radar. The privacy implication is also notable: unlike camera systems, mmWave radar does not capture visual imagery of individuals, making it deployable in environments where cameras face regulatory or consent barriers.
The Training Data Problem — and How MIT Solved It
The fundamental obstacle for any AI model in this space is data scarcity: no mmWave dataset is large enough to train a generative model from scratch. MIT's solution was to simulate mmWave physics on top of existing large-scale computer vision datasets — essentially teaching the AI the language of radar without needing radar-specific training data.
Training large generative models like GPT or Claude requires datasets with millions or billions of examples. mmWave research datasets are orders of magnitude smaller. Collecting sufficient real-world radar data would, as MIT research assistant Maisy Lam explains, have "taken years."
The team's workaround was synthetic adaptation: they took large existing computer vision datasets and computationally imposed the physical properties of mmWave reflections — specularity, noise characteristics, signal geometry — onto the image data. This created a synthetic but physically accurate training set that the generative model could learn from.
The approach represents a broader pattern emerging in Physical AI research: using physics-informed simulation to bootstrap AI training where real-world data is scarce or expensive to collect. The same principle underlies much of the progress in robot manipulation learning, where sim-to-real transfer has become a dominant paradigm.
| System | Task | Signal Source | Accuracy Gain | Sensor Configuration |
|---|---|---|---|---|
| Wave-Former | Hidden object 3D reconstruction | mmWave reflections off objects | ~20% over SOTA | Mobile or fixed radar |
| RISE | Full room scene reconstruction | mmWave reflections off moving humans | ~2× precision over SOTA | Single stationary radar |
What This Means for Warehouse and Industrial Robotics
For robotics buyers and engineers, these two systems address different but equally pressing operational problems: verifying packed items in sealed containers, and enabling robots to understand dynamic environments without full sensor coverage.
Fulfillment and Pack Verification
Warehouse robots currently cannot confirm what is inside a sealed box without opening it. Wave-Former's ability to reconstruct 3D object geometry through cardboard and plastic directly addresses pre-shipment verification — a significant pain point for e-commerce fulfillment, where return rates from mis-packed orders generate substantial cost. A robot equipped with mmWave perception could verify item presence and rough geometry before a box is sealed, without slowing the line.
Smart Deployment for Cobots and AMRs
RISE's single-radar room mapping capability has immediate implications for autonomous mobile robots (AMRs) and cobots deployed in spaces shared with humans. Current human-tracking approaches either require dense camera coverage (with associated privacy concerns) or sensors mounted on the moving robot itself. A fixed radar that builds a live spatial model of the room — including human locations — from ghost signal analysis could enable safer, more responsive cobot operation in dynamic environments.
For teams evaluating robots for these applications, it's worth exploring used industrial robots and cobots currently available on Robot Overflow while tracking how perception systems like Wave-Former progress toward commercial integration.
Timeline to Deployment
Both systems are at research stage, with results to be presented at the IEEE Conference on Computer Vision and Pattern Recognition. The research is supported by NSF, the MIT Media Lab, and Amazon — the last being a significant signal of commercial interest. The team's next stated goal is building foundation models for wireless signals, analogous to GPT or Gemini for language, which would represent a step-change in the generalisability of this approach across environments and object types.