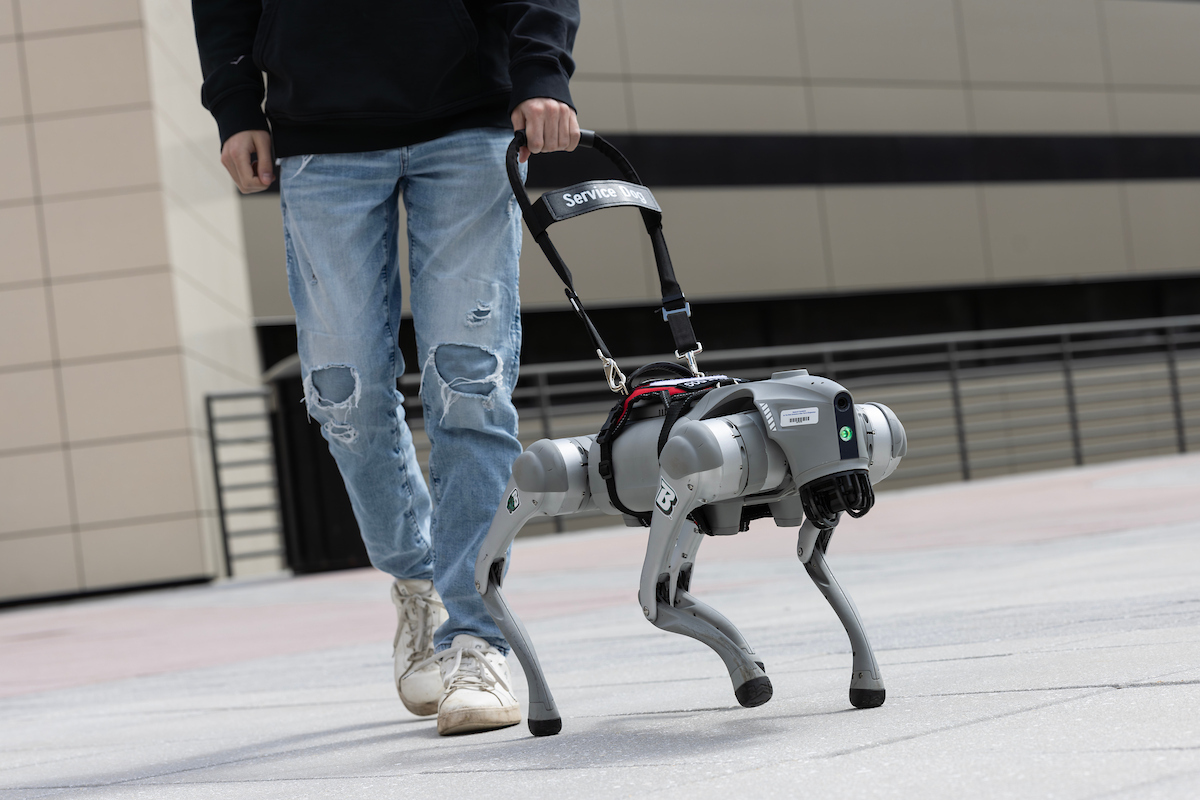
Binghamton University researchers have built a quadruped robotic guide dog that uses GPT-4 to communicate verbally with visually impaired users — describing routes before departure and narrating surroundings during travel. Tested with seven legally blind participants, the system represents a measurable capability leap over biological guide dogs, which typically understand no more than 20 commands.
Table of Contents
- What Did Binghamton University Actually Build?
- How Does It Compare to a Real Guide Dog?
- What Happened During Testing?
- What This Means for Robotics and Assistive Automation
- Frequently Asked Questions
What Did Binghamton University Actually Build?
The system pairs a legged quadruped robot with GPT-4 voice integration, giving it two distinct verbal modes: "plan verbalization" before a journey begins, and "scene verbalization" during navigation. Before moving, the robot describes available routes and estimated travel times. While walking, it narrates the environment — corridors, obstacles, spatial context — in natural language.
This is a meaningful architectural shift. Previous robot guide dog research at Binghamton, led by Associate Professor Shiqi Zhang of the Thomas J. Watson College's School of Computing, focused on leash-pull response systems: the robot reacted to physical cues but said nothing. Layering an LLM on top converts a reactive navigation tool into a conversational navigation partner.
The paper, titled "From Woofs to Words: Towards Intelligent Robotic Guide Dogs with Verbal Communication," was presented at the 40th Annual AAAI Conference on Artificial Intelligence — one of the highest-impact venues in the field, which signals the research has cleared serious peer scrutiny.
According to The Robot Report, similar systems have been explored at the University of Glasgow, and assistive mobility startup Glidance has pursued a wheeled variant — but none have demonstrated the combined pre-journey planning plus live narration loop tested here.
How Does It Compare to a Real Guide Dog?
On pure language bandwidth, the robotic system is not close — it is orders of magnitude ahead. Biological guide dogs comprehend approximately 20 commands at maximum. GPT-4 integration gives the robot essentially uncapped natural language understanding, covering complex multi-part instructions, follow-up questions, and contextual conversation without retraining.
| Capability | Biological Guide Dog | GPT-4 Robotic Guide Dog |
|---|---|---|
| Command vocabulary | ~20 commands | Effectively unlimited (natural language) |
| Route planning verbalization | None | Yes — pre-journey narration |
| Real-time scene description | None | Yes — continuous narration |
| Obstacle avoidance | Yes (trained) | Yes (sensor-based) |
| Emotional support | High | Limited |
| Training time | 18–24 months | Software deployment |
| Availability | ~2% of eligible users | Scalable in principle |
The biological guide dog's advantages are real and not trivially dismissed. Years of trained situational judgment, physical strength for curb negotiation, and the affective bond between handler and animal are not replicated by a quadruped running inference on a cloud API. The analogy breaks down especially in unpredictable outdoor environments where sensory edge cases multiply rapidly.
What the robotic system offers is complementary capability — verbal situational awareness that no biological guide dog can provide — plus scalability. Only an estimated 2% of the 253 million visually impaired people globally have access to a guide dog, according to industry figures. A robotic system does not require two years of specialist training per unit.
What Happened During Testing?
Seven legally blind participants navigated a large, multi-room office environment using the robot. The task: reach a designated conference room. The robot first asked for the destination verbally, presented route options with time estimates, then guided users while narrating the environment — announcing corridor lengths, spatial transitions, and relevant obstacles en route.
Post-navigation questionnaires assessed helpfulness, communication ease, and perceived usefulness. Participants consistently preferred the combined mode — both pre-journey planning narration and real-time scene description — over either mode alone. A parallel simulation study reinforced this finding quantitatively.
Zhang described the participant response as enthusiastic: "They were super excited about the technology, about the robots. They really see the potential for the technology and hope to see this working."
The limitation worth flagging: seven participants in a controlled indoor office environment is a proof-of-concept scale, not a deployment validation. The team explicitly acknowledges this, with plans for expanded user studies, greater autonomy, and both indoor and outdoor long-distance navigation trials. Real-world performance in rain, crowds, and uneven terrain remains an open question.
What This Means for Robotics and Assistive Automation
The Binghamton research matters beyond assistive technology — it is an early demonstration of what happens when you give a legged robot a general-purpose language model as its primary user interface. That architectural pattern has broad implications.
For quadruped platform developers, this is validation that commodity LLM APIs can meaningfully expand the utility surface of existing hardware without custom model training. A Unitree Go2 or similar platform running this software stack becomes a fundamentally different product than its base hardware suggests. Buyers exploring used cobots and mobile robot platforms should note that software upgrades, not hardware replacements, may increasingly define capability tiers.
For the assistive robotics market, the scarcity problem is the real target. Guide dog training organisations globally produce a few thousand animals annually — nowhere near enough to serve demand. Robotic systems that can be manufactured at scale and updated via software represent a structural solution to that bottleneck, assuming outdoor navigation and durability challenges are resolved.
For the broader Physical AI trajectory, the pattern here — legged mobility + multimodal LLM + real-world task execution — is the same architectural stack appearing across humanoid robots, inspection platforms, and logistics systems simultaneously. The Binghamton work is a domain-specific proof point in a much larger convergence. Those tracking the humanoid robot market will recognise the pattern: language-capable embodied systems are moving from labs to structured real-world environments faster than most adoption timelines assumed.
The next frontier for this specific project is outdoor autonomy — handling kerbs, intersections, variable terrain, and pedestrian traffic. That is where the gap between a proof-of-concept and a deployable product lives, and it is not a small gap.