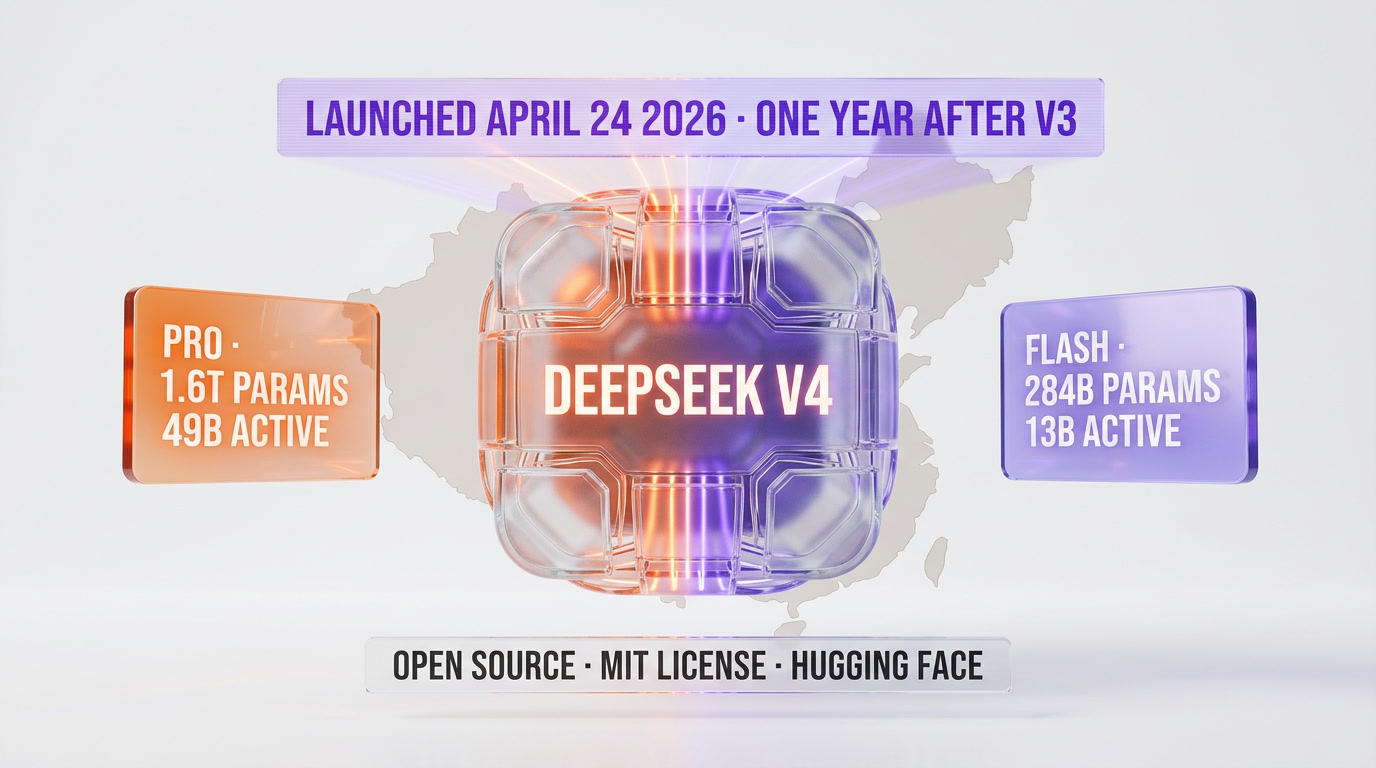
DeepSeek will officially release V4, its latest frontier model, in mid-July with a standard 1-million-token context window across all model variants. The update also introduces an industry-first peak and off-peak API pricing structure that could reshape how developers budget for AI inference costs.
- What DeepSeek V4 Brings
- A New Pricing Model for API Access
- Why This Matters for the AI Industry
- Competitive Landscape
- What This Means for the Industry
- Frequently Asked Questions
- Conclusion
What DeepSeek V4 Brings
The DeepSeek team announced Monday that V4 will ship as the successor to the current preview release, bringing a raft of feature enhancements and performance upgrades. Most notably, the entire model lineup will now support a 1-million-token context window — allowing it to process roughly three full-length novels in a single pass.
Beyond the context expansion, DeepSeek V4 delivers stronger performance in agent-based task execution, mathematical reasoning, and code generation. According to TechNode, the model shows “stronger performance in areas including agent-based task execution, mathematical reasoning, and code generation” compared to the preview version.
These improvements position V4 as a direct competitor to models like OpenAI’s GPT-4o, Anthropic’s Claude 3.5, and Google’s Gemini 1.5 Pro — all of which have been battling for dominance in long-context understanding and complex reasoning tasks.

A New Pricing Model for API Access
Perhaps the most strategic shift DeepSeek is making with V4 is its new API pricing structure. For the first time, the company will introduce dynamic pricing based on time of day — a model common in cloud computing but rare in the AI API market.
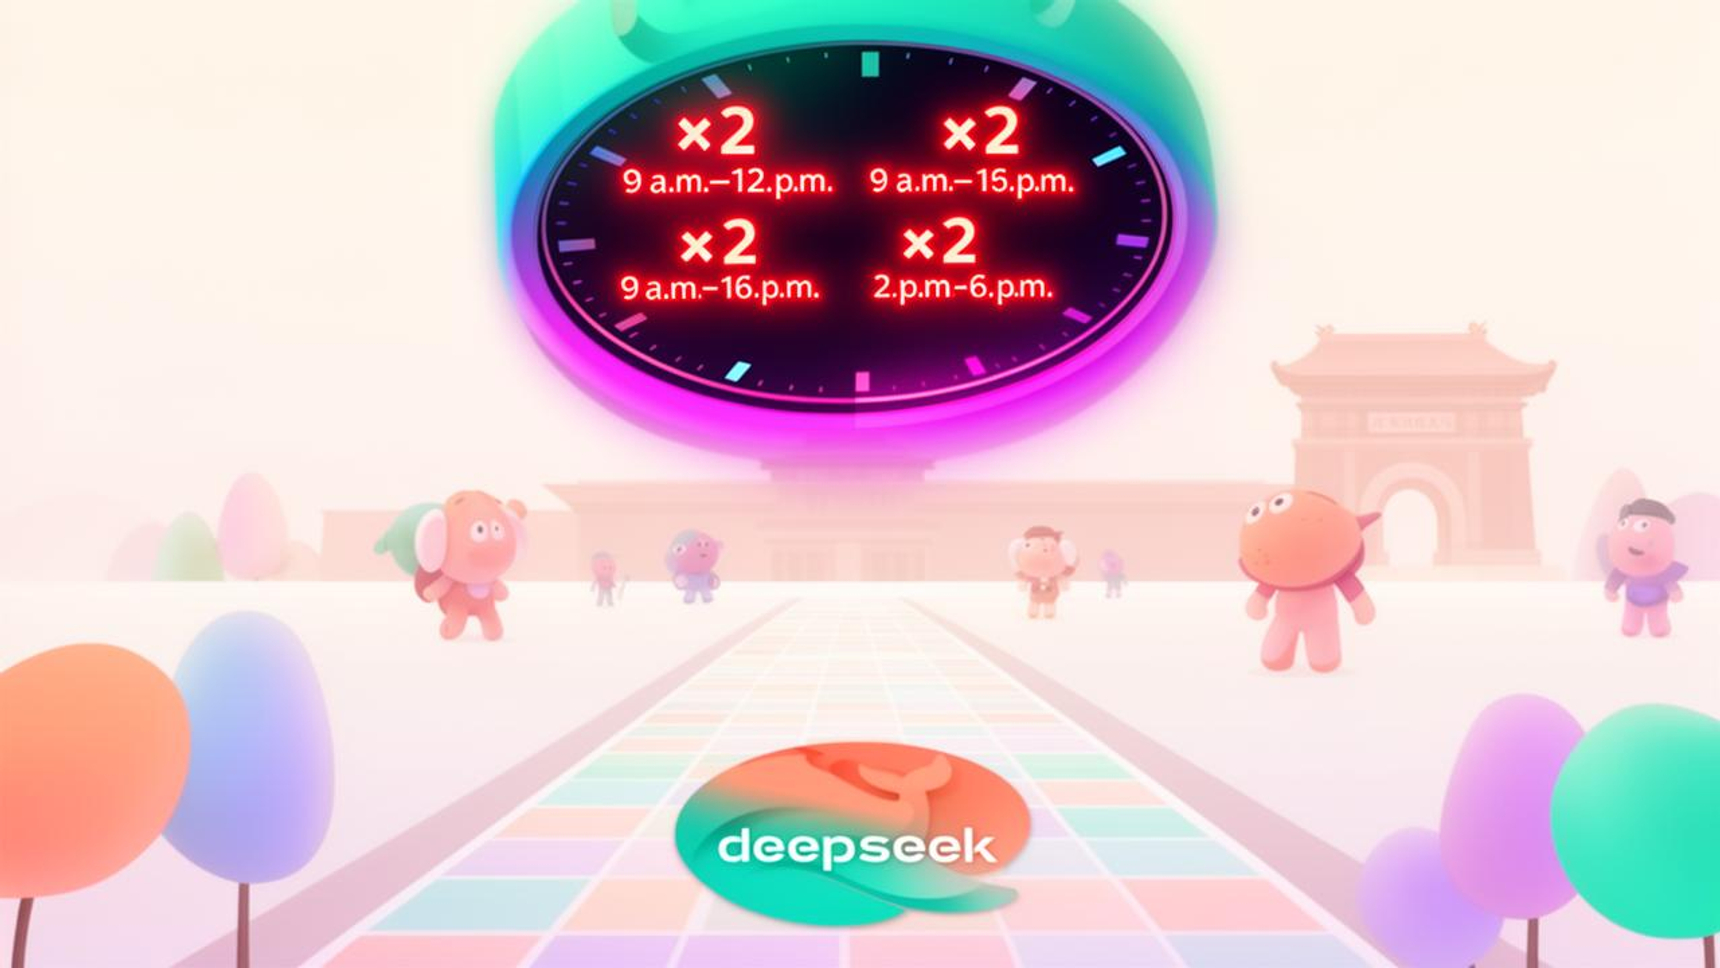
Peak hours are defined as 9:00 a.m. to 12:00 p.m. and 2:00 p.m. to 6:00 p.m. each day, during which API usage will be charged at twice the off-peak rate. Off-peak periods include all other hours, likely incentivizing developers to batch heavy workloads to non-peak windows.
The move mirrors strategies used by cloud providers like AWS and Azure to smooth demand, but it’s unusual for AI model APIs. Most providers — including OpenAI and Anthropic — use flat per-token pricing with possible volume discounts. DeepSeek’s approach could prompt others to follow suit as AI inference costs remain a major concern for startups and enterprises.
Why This Matters for the AI Industry
DeepSeek V4’s launch is significant on multiple fronts. First, the 1-million-token context window matches or exceeds the capabilities of top-tier Western models. Gemini 1.5 Pro also offers 1M tokens, while GPT-4o maxes out at 128K and Claude 3.5 at 200K. DeepSeek now offers developers and enterprises an alternative that can handle extremely long documents — legal contracts, codebases, research papers — without chunking.
Second, the peak/off-peak pricing demonstrates that Chinese AI labs are becoming more commercially sophisticated. DeepSeek, backed by hedge fund High-Flyer, has already proven it can train competitive models at a fraction of the cost of US counterparts. With V4, it’s now innovating on the business model side as well.
According to TechNode, the pricing change goes live alongside the official release in mid-July. Developers should expect the off-peak rates to be significantly cheaper, though exact dollar amounts have not yet been published.
Competitive Landscape
DeepSeek V4 enters a market where several frontier models are vying for developer mindshare. OpenAI recently updated GPT-4o with improved vision capabilities, Anthropic launched Claude 3.5 with a 200K context window, and Google continues to push Gemini 1.5 Pro with its own 1M context.
DeepSeek’s differentiators are price and open research contributions. The company has published detailed technical reports on its Mixture-of-Experts architecture and training methods, earning credibility in the AI research community. V4’s improved agent-based execution could also appeal to developers building autonomous workflows — a hot area as the industry moves beyond simple chat completions.
The peak/off-peak pricing gives DeepSeek another lever: developers with flexible scheduling can dramatically reduce costs, potentially undercutting Western rivals even further. For companies that process large volumes of text overnight or over weekends, V4 could become the most cost-effective option.
What This Means for the Industry
For developers and startups: The 1M-token context window unlocks new use cases — analyzing entire code repositories, processing long legal documents, or summarizing multi-hour meeting transcripts. The pricing model also allows startups to manage costs more predictably by shifting non-urgent workloads to off-peak hours.
For enterprises: DeepSeek V4 offers a compelling alternative for organizations that need long-context AI but are wary of vendor lock-in. The Chinese lab’s track record of releasing models under permissive licenses (like Apache 2.0) may appeal to companies that want to self-host or fine-tune.
For competitors: OpenAI and Anthropic may feel pressure to introduce dynamic pricing or expand context windows further. The current flat-rate API pricing model could become a competitive disadvantage if DeepSeek’s off-peak rates prove significantly cheaper. Western labs may also accelerate their own context-window expansions to avoid losing high-value use cases.
For investors: DeepSeek V4’s launch reinforces the narrative that Chinese AI labs are not just catching up but innovating in business models. This could affect funding dynamics — US VCs may push their portfolio companies to adopt similar pricing strategies, and cloud providers might bundle AI inference with compute time more aggressively.
Conclusion
DeepSeek V4 marks a notable step forward for the Chinese AI lab, delivering a massive context window and a novel pricing model that could influence the entire API industry. By combining technical improvements with a smarter pricing strategy, DeepSeek is positioning itself as a serious contender in the global frontier model race — and forcing competitors to rethink their own approaches to cost and access.